Model Training & Machine Learning
Predictive Models|Language Model Adaptation|Reproducible Training
Sphere 10 builds models for decisions your organisation needs to make: forecasting demand, classifying documents, detecting anomalies, recognising images or adapting a language model to a defined task. We own the work from dataset construction and experimental baselines through to a reproducible model artefact and a usable application interface.
Custom training is useful when a defined decision needs more than a prompt or a search over documents. Examples include classifying incoming documents, prioritising an enquiry for staff, forecasting demand or detecting an operational anomaly. We agree the input available at decision time, the result the application needs and the cost of a wrong prediction before choosing the model.
Choose the Training Method From the Task
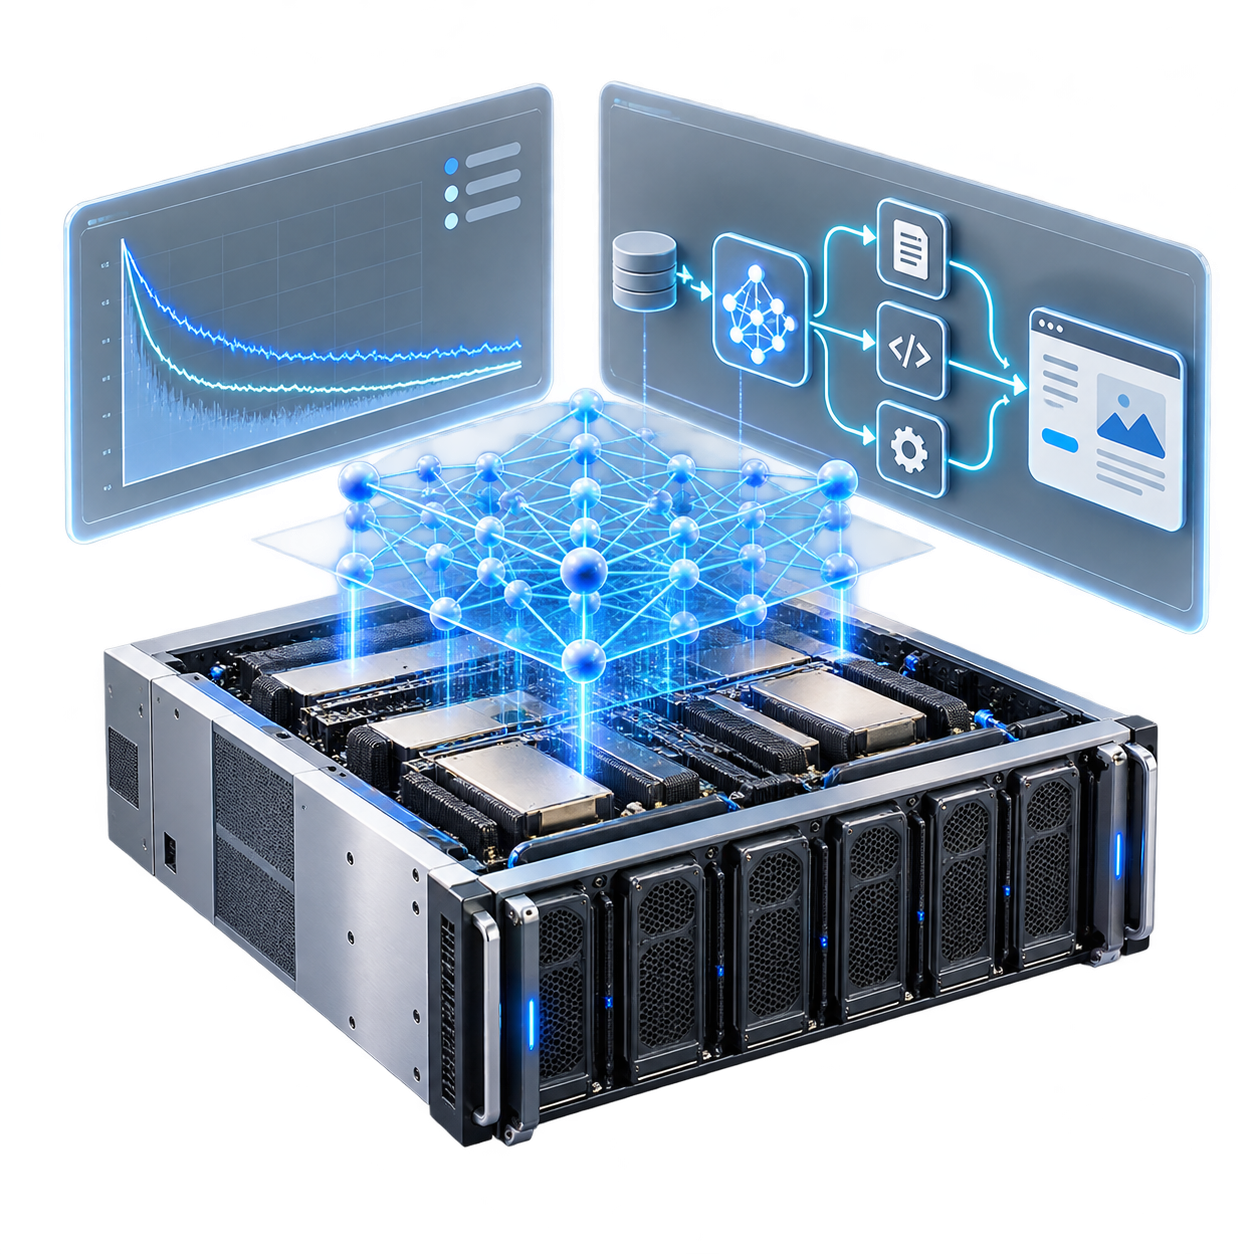
A training engagement starts with the prediction target and the cost of being wrong. We inspect how labels are produced, whether historical data reflects future use and whether the proposed inputs will actually exist at prediction time. Time-based and entity-based splits are used where random splitting would leak information between training and evaluation.
For structured business data, we compare conventional statistical or tree-based approaches with ML.NET and Python tooling. Deep learning and language-model adaptation use PyTorch, Hugging Face Transformers and PEFT where suitable. LoRA or quantised adaptation can reduce the trainable footprint, but the choice follows model compatibility, hardware capacity and measured quality. Training from scratch is separately scoped when the data and compute justify it.
Use the Model Where It Improves the Decision
Model adaptation is separately justified. An internal assistant may need better source material or retrieval rather than new weights. A marketing workflow may need approved examples, prompts and review criteria rather than training from scratch. Where adaptation is warranted, its dataset, held-out evaluation and deployment target become explicit deliverables.
Deliver an Experiment You Can Reproduce
Integrate Predictions Into .NET
ML.NET provides a native .NET route for suitable predictive pipelines. For Python-trained models, we evaluate a service boundary or ONNX execution against the actual operators and target hardware. Conversion is verified with representative inputs; a successfully exported file alone does not establish equivalent predictions.
Sphere10 Framework contributes data-access scopes, serialization and application composition around the model. Those mechanisms support controlled ingestion and persistence of results. They are separate from PyTorch or ML.NET training, and we keep that boundary explicit in the delivered design.
Acceptance Includes the Weak Cases
We agree evaluation measures before tuning: precision and recall, forecast error, false-positive cost, response time or another measure tied to the business decision. Acceptance covers unseen examples and degraded inputs, not just the demonstration dataset. You receive the training code, environment specification, model artefacts and retraining instructions, with limitations and drift indicators documented. A later change to labels, features or data distribution can then be assessed as a controlled model revision.
For a document or knowledge project, bring representative examples and the decisions staff make from them. We agree which formats, labels, missing fields and weak cases the build must handle. The accepted model package then feeds the reviewed document, sales or operational workflow through the application contract; new labels or business rules are a controlled scope change.
Platforms & Tooling
.NET ML.NET PyTorch Hugging Face PEFT scikit-learn XGBoost ONNX Runtime MLflow
Discuss Your AI Project Back to AI Services